Enterprise AI & Strategy · Architecture
AI System Design for Enterprise: From Data to Reliable Decisions
Follow a travel-expense claim from receipt to finance review—and see how data, models, business rules and controls fit into one enterprise system.
By Dr. Nabanita Sinha · October 6, 2026
Watch on YouTube
How to Design Enterprise AI Systems
Open video on YouTubeStart with a real business use case
Travel-expense claim automation
Today, employees manually enter receipt details, look up reimbursement rules and follow up on incomplete claims. Finance repeats many of the same checks. The opportunity is to automate routine preparation and validation, reduce avoidable back-and-forth, and retain human approval. Define that business problem first; then decide whether a form, chatbot or controlled agent is the right interface.
1. Start with the business problem
I use travel-expense claim automation as a practical example of enterprise AI system design. Let’s consider a fictional employer where employees prepare reimbursement claims manually and finance checks each submission. The business problem is repeated data entry, incomplete evidence and avoidable review cycles—not the absence of a chatbot.
The current manual process
After a business trip, an employee collects receipts, types the merchant, dates, amounts and expense categories into a form, attaches the documents, searches for the applicable reimbursement policy and submits the claim. Finance checks the totals, eligibility, supporting evidence and possible duplicates. Missing information or an incorrect policy sends the claim back to the employee, creating another round of emails and corrections.
Routine work that can be automated
| Manual work today | Practical automation | Control to retain |
|---|---|---|
| Re-enter receipt details | Use OCR or document extraction to prefill structured claim fields. | Let the employee correct fields; request clarification for unreadable evidence. |
| Find policy limits and check totals | Apply approved, versioned rules in code; retrieve authorized policy evidence to explain the result. | Escalate ambiguous eligibility or conflicting policies rather than inventing a rule. |
| Identify missing evidence and possible duplicates | Validate required fields and compare claim identifiers and receipt details with existing records. | Treat uncertain matches as review flags, not automatic accusations. |
| Prepare, route and follow up on the claim | Build a checked draft, submit through the approved API and display the recorded status. | Require employee confirmation, current authorization and duplicate-safe submission; keep finance approval and payment in the existing controlled workflow. |
Define success before selecting AI: measure claim-preparation time, manual field corrections and returns for missing information against the current process. The objective is less routine work and fewer avoidable corrections without increasing incorrect claims, unauthorized access or duplicate submissions. No improvement should be assumed before it is measured.
Then design the chatbot or agent around the workflow
A form with receipt upload and guided corrections may be enough. Add a chatbot when employees need conversational help understanding policy or supplying missing details. Use a controlled tool-using workflow or agent only when it needs to retrieve evidence, prepare a draft or invoke a permitted action. Give it narrow tools, validate every tool request in application code and require confirmation before submission. The interface serves the business process; it does not replace the claim record or finance controls.
Keep straightforward checks—required fields, arithmetic and encoded policy limits—in deterministic code. Use AI where it adds value, such as interpreting receipt content or explaining authorized policy evidence. If a fixed sequence can reliably complete the task, start there rather than giving an agent open-ended autonomy.
Validate a complete workflow in a proof of concept
A meaningful PoC tests a small, complete workflow: take a sample receipt and trip details, extract the claim fields, validate them, look up the relevant policy, and produce a draft with evidence and reasons for any exception. Test clear receipts, unreadable receipts, missing information and duplicates. Compare the result with a manually checked baseline.
The business use case comes first; the PoC is the starting point for testing the proposed solution. Agree on success criteria before building it. A successful PoC should demonstrate:
- Business value: a measured improvement over the manual or simpler baseline on representative cases—not just one impressive example.
- End-to-end correctness: receipt fields, rule checks, cited explanations and the recorded draft agree with human-reviewed expected results.
- Safe failure: missing evidence, ambiguous policy, invalid inputs and denied actions produce an explicit exception or review path, not an invented answer or unauthorized submission.
- Integration feasibility: the draft fits a validated schema, the simulated submission respects the intended API contract, and duplicate requests or timeouts have a defined recovery path.
- A credible next step: repeatable results, known limitations and initial latency and cost measurements justify a controlled pilot—or show why the approach should change. A small PoC does not establish production-scale reliability.
Keep this prototype in a sandbox using synthetic or appropriately approved data. Submission can be simulated, but it should use an explicit request schema and return a recorded claim ID or a clear failure. It must not send real payments. Moving to production then adds live identity, current access rights, secure integrations, traffic handling, monitoring and accountable owners.
The workflow to design, step by step
- Capture: collect the receipt, trip dates, expense category and the authenticated employee’s context.
- Extract and confirm: turn document content into structured fields; ask for correction when the receipt is unclear or required fields are missing.
- Check: apply authorized policy rules, validate totals and dates, and check for possible duplicates.
- Draft and explain: prepare the claim, cite the applicable policy and separate satisfied checks from unresolved exceptions.
- Confirm and submit: show the exact draft to the employee; submit through an authorized, idempotent API only after confirmation.
- Review and track: let the existing finance workflow approve, reject or request corrections, and return the claim’s recorded status.
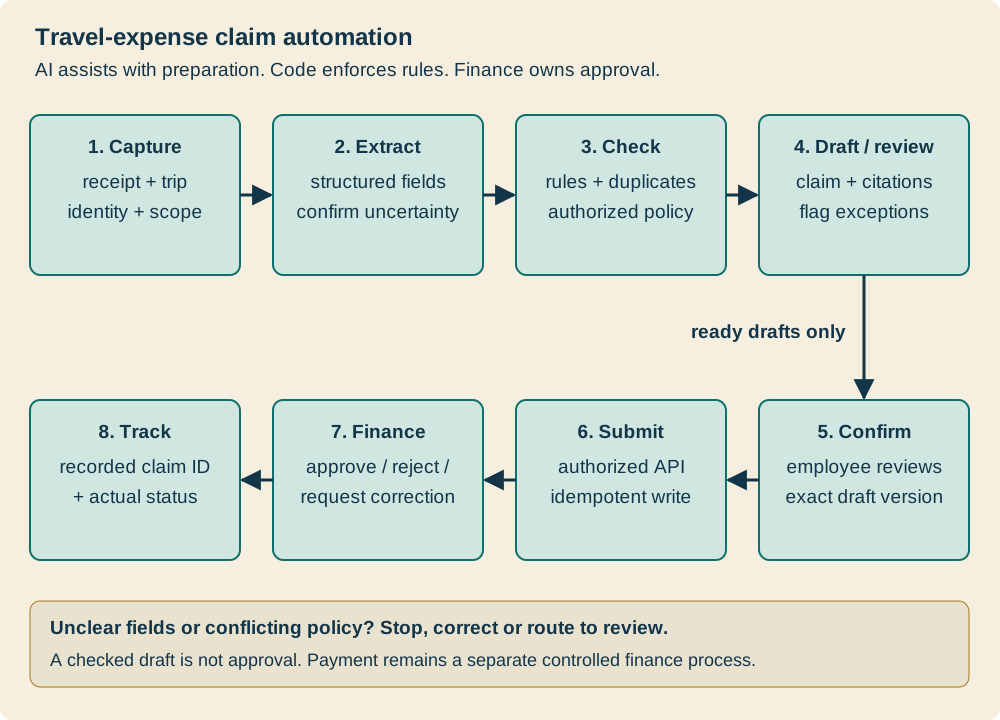
System design describes the components, their interfaces and the movement of data between them. High-level design identifies the major services and trust boundaries. Low-level design specifies details such as API schemas, timeouts, queue behavior, authorization checks and error handling. Both matter; a diagram without those contracts is not an implementation plan.
The following sections connect each technical decision to this workflow. This is an illustrative design, not a claim about a deployed customer system or any employer’s actual reimbursement policy.
2. Translate the business problem into requirements and constraints
Before choosing a model, define the task. For this use case: prepare a complete, policy-checked expense claim with less manual entry, without unauthorized access, duplicate submission or bypassing finance approval. Compare it with the current manual form and rules-based process, not only with another chatbot.
- Business outcome: reduce claim-preparation time and avoidable finance returns without increasing incorrect or duplicate claims.
- Users and access: who can use the service, which tenant or business unit they belong to, and which documents each identity can read.
- Quality: measure extracted-field accuracy, rule-check correctness, citation accuracy and appropriate escalation when information is missing.
- Service targets: define availability, peak request rate, tail latency and the age of the underlying policy data. For an LLM, measure both time to first token and time to the completed answer.
- Risk boundaries: specify restricted data, permitted actions, human-review requirements, data retention and where providers may process information.
- Cost: set a budget per successful task, not just per model call. Include retrieval, retries, infrastructure and review effort.
A worked example: assume an approved fictional policy allows a hotel expense up to ₹4,000 per night, including applicable taxes. A receipt shows two nights at ₹3,900 each, totalling ₹7,800. The nightly-cap check passes under those assumptions. That alone does not mean the claim is approved: trip eligibility, dates, duplicate checks, required evidence and the finance approval route still matter. If nightly amounts cannot be determined, the system should request the itemized bill rather than assume that the total was divided equally.
These are design choices, not universal benchmarks. A fraud-scoring service may need a much tighter response deadline than a document-summary job. A slower answer can be acceptable; an unauthorized answer cannot.
3. Choose the simplest AI pattern that solves the problem
Not every enterprise AI system needs a vector database, a feature store, a GPU cluster or multiple agents. Start with the workload, then choose the components.
| Pattern | Typical task | Important design requirement |
|---|---|---|
| Predictive ML | Fraud score, demand forecast, ranking | Consistent features, reliable labels, calibrated outputs where needed, and outcome monitoring |
| Generative AI with RAG | Answer using internal policies | Authorized retrieval, fresh evidence, bounded context and evidence-based evaluation |
| Tool-using workflow or agent | Draft a ticket, then propose an update | Independent authorization, validated tool arguments, bounded execution and approval of sensitive actions |
RAG, or retrieval-augmented generation, supplies relevant external information to a model at request time. It does not retrain the model and does not guarantee a correct answer. Fine-tuning changes model weights to improve learned behavior for a task; it is not a replacement for checking current facts or enforcing access rights.
For the claim workflow, use document extraction to read the receipt, deterministic code to validate arithmetic and encoded policy rules, and permission-aware RAG to explain the relevant policy with citations. Use a controlled API workflow to create the claim. An optional predictive model can prioritize suspicious cases for review; a risk score is not proof of fraud and should not, by itself, authorize a payment or reject a claim.
A fixed, testable workflow is the starting point here—not a collection of autonomous agents. Keep monetary limits and eligibility rules in an approved, versioned rule configuration. If a policy is ambiguous or cannot be reliably represented as a rule, route the case to review. Multiple agents add coordination, latency, cost and failure modes; they do not automatically improve reliability.
4. Separate preparing knowledge from answering a request
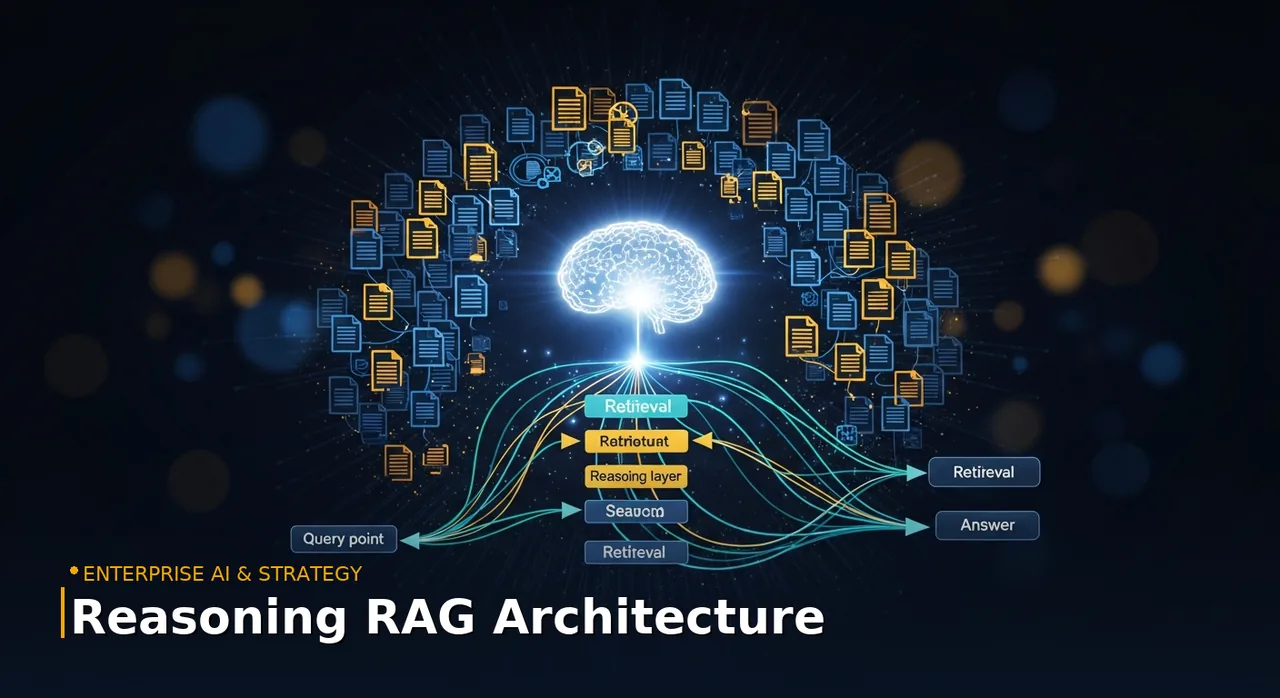
Policy explanation is one part of the claim workflow, not the whole product. It has two paths: the preparation path indexes approved policy documents, while the request path retrieves the rules relevant to this employee, trip and expense. Keeping policy preparation outside the live request reduces avoidable delay; reading a newly uploaded receipt remains part of that claim’s processing.
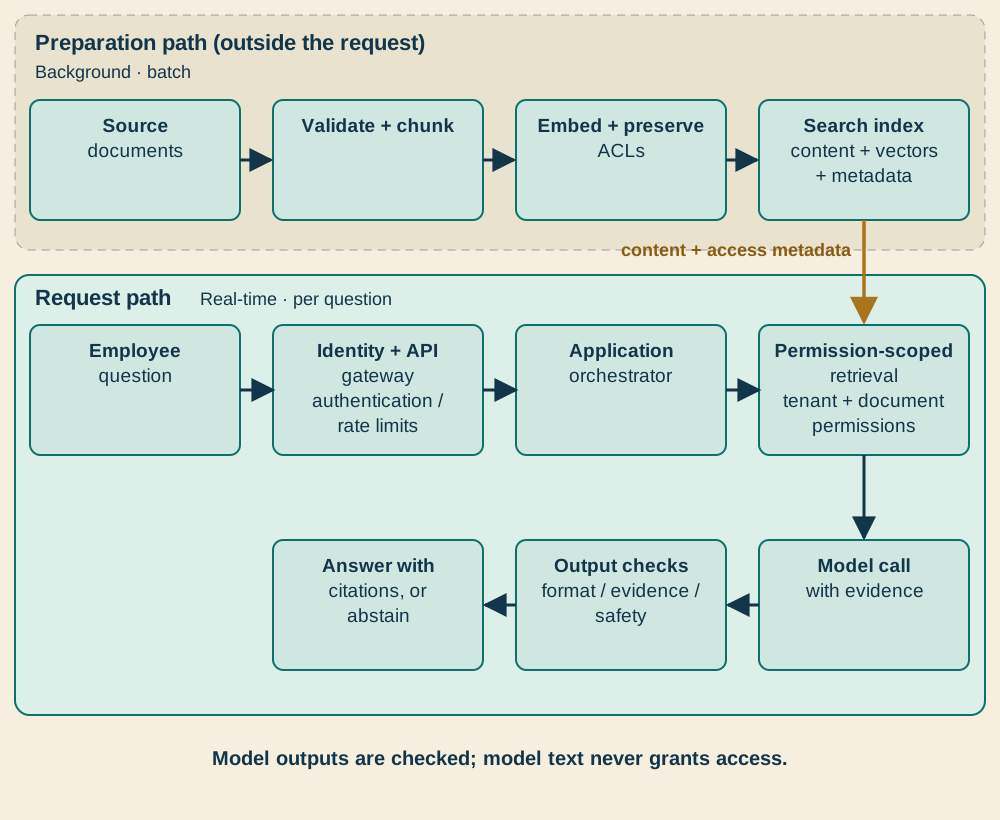
Preparation: make knowledge searchable
Connect to approved repositories, validate content, extract readable text and divide it into meaningful chunks. Retain the source ID, document version, effective date, tenant and access-control metadata. An access-control list (ACL) identifies who may read a document; preserve that information alongside each indexed chunk. Create embeddings for semantic search where useful, and store them with the text and metadata. A search engine can support keyword and vector retrieval together; a separate vector database is not always necessary.
Request: retrieve evidence, then answer
- Authenticate the employee. The gateway checks identity, applies rate limits and establishes a trusted user and tenant context.
- Orchestrate the task. Application code validates the request, selects the allowed workflow and sets time and token limits.
- Retrieve within permissions. Search applies tenant and document-level authorization before evidence is sent to the model. Optional reranking orders authorized candidates by relevance.
- Build bounded context. Combine task instructions, the question and relevant evidence without exceeding the model’s context budget. Mark retrieved material as data, not as trusted instructions.
- Run inference and check the output. Validate expected structure and assess evidence support, citation validity and safety. These checks reduce risk; they cannot prove every statement is true.
- Return an answer or abstain. Show the applicable policy and source. If evidence is insufficient or the request is outside scope, explain the limitation and route to a human or the underlying search results.
Authentication answers “Who is this?” Authorization answers “What may this person access or do?” An authenticated employee is not authorized to read every indexed document. The prompt must never be the access-control mechanism.
5. Design data freshness, lineage and consistency explicitly
The data layer needs more than storage. It needs a clear contract: which fields are required, which source is authoritative, how changes are detected, and what happens when a record is malformed or late.
Choose storage by the job it must do
A vector database is not the system of record for expense claims. Start with the enterprise’s existing finance system and approved storage; add components only when the workload requires them.
| Data and purpose | Suitable storage | Design requirement |
|---|---|---|
| Claims, line items, approvals and status | A relational database such as PostgreSQL or SQL Server, or the finance platform’s authoritative records | Transactions, constraints, controlled state changes and tenant-scoped access; identify one authoritative owner for each record. |
| Receipt images, PDFs and original policy documents | Encrypted object storage | Keep object references and provenance in the claim record; enforce access, retention and deletion policies. |
| Policy text and semantic retrieval | A search index with keyword and optional vector support, or a relational vector extension | Preserve source versions and access metadata; evaluate retrieval quality before adding a dedicated vector store. |
| Flexible extraction payloads and short-lived cached results | Validated JSON in the existing database, or a document store when justified; an optional key-value cache for temporary reuse | Validate structure and expiry. Neither raw model output nor a cache is authoritative claim or approval state. |
Define the schema before connecting the model
For this illustrative design, define a Claim record with claim ID, tenant ID, authenticated employee ID, trip dates, currency, status, policy version and record version. Link separate ClaimItem records containing expense category, merchant, expense date, amount and receipt reference. Keep extraction results distinct from employee-confirmed values, and record approval and audit events with actor, time and outcome.
Use decimal monetary values or a currency-aware integer minor-unit representation—not floating-point arithmetic. Validate required fields, supported currencies, date ranges and item totals. Derive employee and tenant identity from trusted authentication, not from model-generated fields. Define allowed states such as draft, submitted, needs correction, approved and rejected, and enforce who may move a claim between them. Use foreign keys and appropriate uniqueness constraints; enforce duplicate-safe submission with an idempotency key scoped to the caller and operation.
Make integration contracts explicit
Connect the identity provider, policy repository and finance platform through narrow, versioned APIs. Specify request and response schemas, required fields, error codes, authorization scopes, timeout budgets and correlation IDs. Validate model-generated arguments on the server before any tool call. For example, a submit operation accepts a confirmed draft ID and version plus an idempotency key; it returns an authoritative claim ID and recorded status, or a clear pending or failure result.
A local database transaction cannot by itself make a remote finance API call atomic. Where local state changes must publish work, use a transactional outbox or an equivalent durable mechanism, idempotent consumers and reconciliation with the finance system. After a timeout, query the recorded outcome before retrying. Plan backward-compatible schema changes, migration tests and authenticated event delivery so an integration update cannot silently corrupt claims or lose status changes.
Keep data current and traceable
- Ingest deliberately. Use scheduled batches for slow-changing information, events or change-data capture for faster updates, and a queue when producers and consumers need independent capacity. Kafka or another streaming system is useful when justified—not a default requirement.
- Validate before use. Check schema, missing values, duplicates and source integrity. Quarantine bad records rather than silently publishing them.
- Track provenance. Keep source IDs, transformation versions and timestamps so a result can be traced to the information that produced it.
- Propagate changes and deletions. Updated content, revoked permissions and removed documents must reach indexes and caches. Define synchronization delays and what the service does when permission freshness cannot be established.
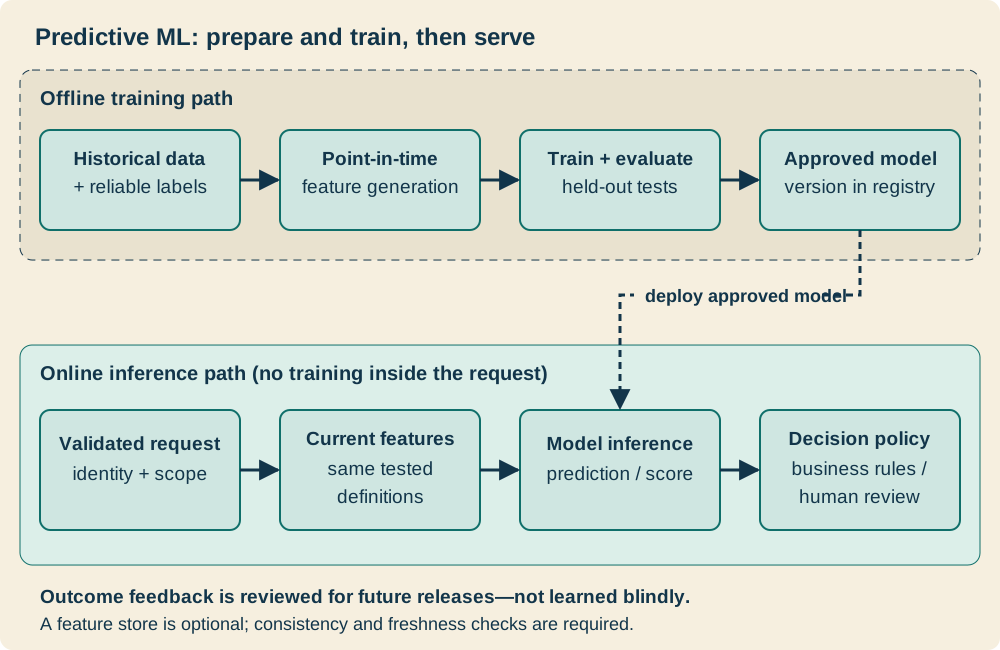
For predictive ML, training needs historical features as they existed at the prediction time. A point-in-time join prevents accidentally using future information. Use shared, tested feature definitions and validate freshness in serving. A feature store can help manage online and offline features, but it does not eliminate training–serving skew by itself.
For RAG, chunk size and overlap are evaluation choices, not fixed rules. Chunks should preserve enough meaning to answer the question while keeping context manageable. If the embedding model changes, document and query embeddings must remain compatible; plan a reindex or a versioned migration rather than mixing incompatible vectors.
In the claim workflow: preserve the original receipt securely, record the extracted fields separately from employee corrections, and keep a trace of which policy and rule versions were applied. When a limit changes, select the policy by its documented applicability rules—for example, the trip or expense date if the policy specifies that—not simply the newest document. Employee permissions must still be checked against current authoritative access controls.
6. Make serving reliable before making it complex
The serving layer runs the model and exposes its output to the application. It may call a managed provider or run a self-hosted model. Managed services reduce infrastructure work but introduce provider limits, outage dependencies and data-processing requirements. Self-hosting offers more operational control, but the team owns capacity, patching, hardware efficiency and model operations.
Scale the actual bottleneck
Horizontally scaling API servers will not fix a saturated model endpoint. Measure gateway, retrieval, reranking, model and tool latency separately. Keep training and bulk indexing workloads from consuming resources reserved for live inference.
For an illustrative load estimate, 20 requests per second with an average end-to-end time of 6 seconds means roughly 120 requests in flight in a stable system, using Little’s law. That is an initial capacity estimate, not a recommended target: bursts, token lengths and provider limits still require load testing and headroom.
- Bound work: cap input size, output tokens, queue depth and concurrent requests. Apply backpressure instead of accepting unlimited work.
- Set deadlines: allocate timeouts to each stage; cancel unnecessary downstream work when the overall deadline expires.
- Retry selectively: use bounded retries with backoff and jitter for transient failures. Do not retry denied access. Repeating a write requires idempotency protection.
- Fail safely: circuit breakers stop repeated calls to a failing dependency. If the model is unavailable, offer authorized search results or human help—not an invented response.
- Choose synchronous or asynchronous: answer short interactive requests inline; submit long document-processing jobs to a queue and return a job ID with status.
Optimize cost without weakening isolation
Model cost depends on input tokens, output tokens and any provider-specific charges. Total task cost also includes embeddings, search, storage, compute, retries and review. Use the smallest model that passes the task’s evaluations, limit unnecessary context and consider batching when the added waiting time is acceptable.
Caches must respect identity, tenant, permissions, evidence freshness and model/prompt versions. A semantic cache can return a superficially similar but inapplicable answer, so bypass it for sensitive or rapidly changing decisions. Provider prompt caching or attention-key/value caching is not the same as reusing a final answer. Streaming improves perceived responsiveness but does not guarantee a faster completed answer or make unchecked output safe.
In the claim workflow: receipt processing can be queued and expose a recorded status such as “processing” or “needs correction.” The employee should not have to keep a chat open while extraction runs. If a submission request times out, check the finance system’s recorded result using the same idempotency key before retrying; otherwise a slow response can become a duplicate claim. Define one authoritative claim record and controlled state transitions instead of inferring status from chat text.
7. Security belongs in code and infrastructure—not just prompts
Enterprise AI inherits normal application risks and adds model-specific ones. Use encryption, secret management, least-privilege service identities, tenant isolation, restricted network access and auditable access decisions. Assess model-provider retention, training-use policies, processing locations and contractual obligations before sending enterprise data.
Retrieved documents, web pages and tool results can contain instructions designed to manipulate the model. This is indirect prompt injection. Delimiting evidence and using detection checks can help, but there is no complete prompt-only defense. Keep confidential information and dangerous capabilities behind independently enforced boundaries.
If the assistant can take actions
Use this controlled sequence: propose action → validate typed arguments → authorize in the user’s scope → obtain required approval → execute a narrow tool → record the outcome. The model may propose an action, but application code and the downstream system decide whether it is allowed.
For the expense claim, show the employee the exact merchant, dates, currency, amounts, attachments and policy-check results before submission. Bind confirmation to that draft version; editing it invalidates the previous confirmation. The submission service must authorize the employee, revalidate the draft and write with an idempotency key. After submission, finance retains its own approval workflow. Do not give the model a payment tool or permission to change bank details. Bound workflow steps, tool calls, elapsed time and spending.
A protocol such as MCP can standardize how tools are exposed; it does not replace authorization, approval or audit controls. Similarly, splitting work among multiple agents does not create a security boundary.
8. Evaluate the whole system, not just model accuracy
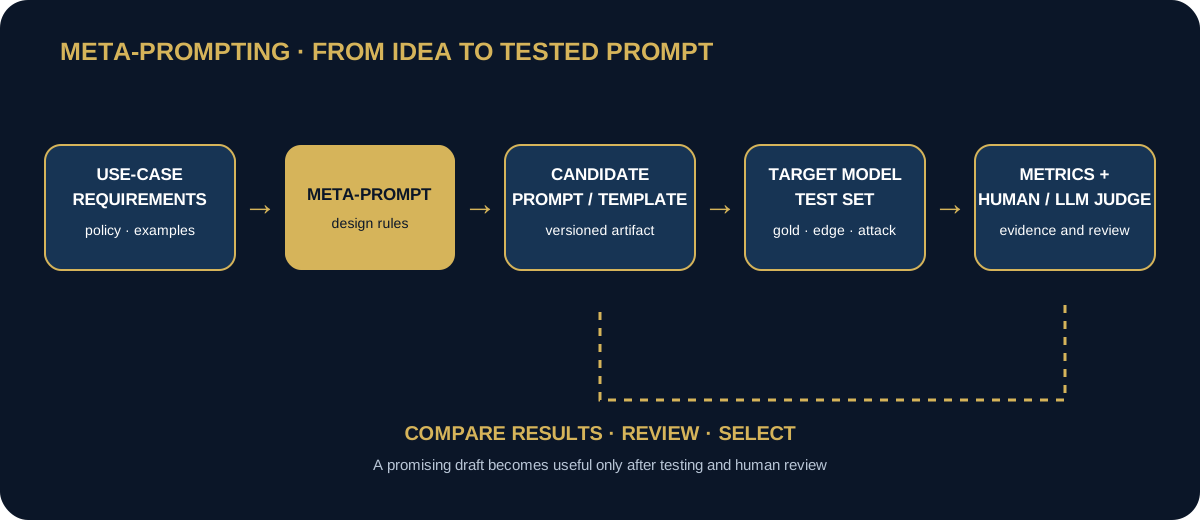
A model can pass a standalone test while the application still retrieves the wrong policy or exposes a restricted source. Build a versioned evaluation set from representative tasks, edge cases and adversarial cases. Keep a held-out set separate from the examples used to tune prompts or models.
| Layer | What to measure | Example failure |
|---|---|---|
| Retrieval | Relevant-source recall, ranking quality, freshness and permission isolation | The current policy is indexed but never retrieved |
| Answer or prediction | Task correctness; evidence support and citation accuracy for RAG; suitable precision/recall and calibration metrics for classifiers | A confident answer contradicts the cited policy |
| Safety and actions | Injection resistance, data leakage, authorization checks and tool execution correctness | A restricted document appears in another tenant’s response |
| Service | p95/p99 latency, availability, error and timeout rates, queue depth and cost per successful task | Average latency looks good while peak users time out |
| Business outcome | Useful task completion, reviewer corrections, appropriate escalation and time saved against a baseline | Fluent answers create more follow-up work |
For the claim workflow, test illegible receipts, incorrect totals, currency mismatches, boundary dates around policy changes, duplicate invoices and modified drafts after confirmation. Also test missing policy evidence, conflicting versions, revoked access, malicious instructions inside receipts and provider outages. Verify the structured result and final recorded claim status—not just whether the explanation sounds helpful. Inspect slices such as departments, languages and receipt types; a good aggregate score can hide weak performance for one group.
LLM-based judges can help scale evaluation, but their scores are not objective ground truth. Calibrate them against human-reviewed examples and use deterministic checks for properties such as schema validity and permission enforcement. For predictive ML, delayed outcomes mean live accuracy may not be immediately observable; use operational signals while waiting for reliable labels.
9. Treat every update as a controlled release
The effective AI product is a bundle: application code, model version, prompt templates, feature definitions or retrieval configuration, index version, policies and thresholds. Record compatible versions together. A prompt or index change can alter behavior even when the model stays the same.
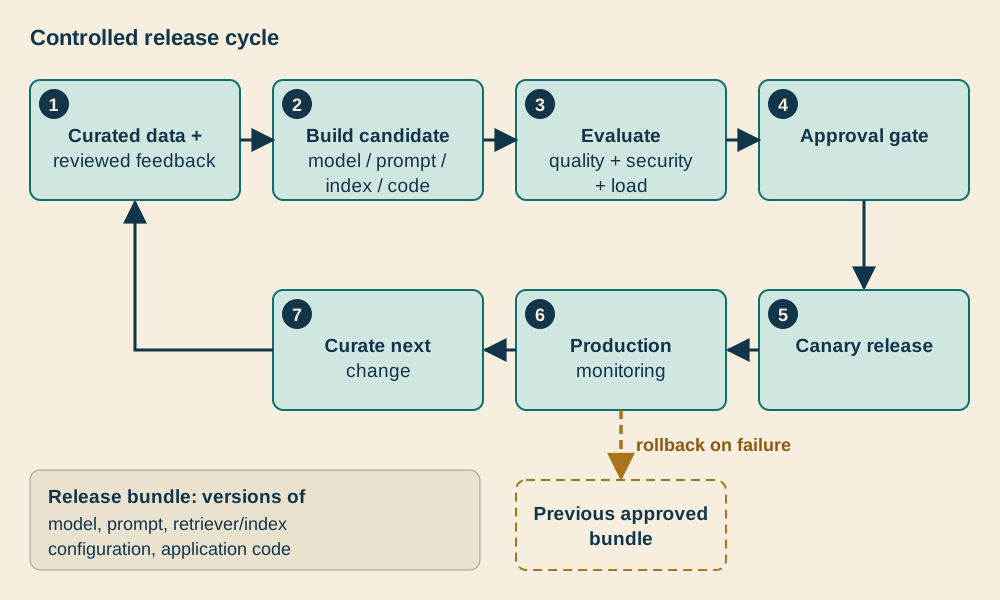
For predictive ML, the build step may include retraining. For an application using a hosted foundation model, it may only change a prompt, retrieval strategy or provider model version. Both still need regression tests and release controls.
- Shadow testing: send a copy of live input to a candidate without allowing it to affect the user or perform real write actions.
- Canary deployment: expose a small, controlled share of traffic to the candidate and compare quality, latency and cost against agreed thresholds.
- Rollback: return to the previous approved compatible bundle if release criteria fail. Test this route before an incident.
Monitor traces across gateway, retrieval, model calls and tools using a shared request ID. Record configuration versions, latency, token usage and error categories. Protect logs with access controls and retention limits; avoid storing raw sensitive prompts and responses by default.
Drift is a signal to investigate, not proof that retraining is needed. A changed input distribution, a new policy document and a drop in answer quality are different problems. The right fix might be a data correction, reindex, permission update, prompt change or model update. Review and deduplicate feedback before using it for evaluation or training, and check labeling quality and data-poisoning risks.
Assign operational and risk owners. NIST’s voluntary AI RMF provides a useful structure for governing the use case, mapping its context, measuring risks and managing them. Following a framework does not by itself establish legal compliance.
In the claim workflow: finance corrections become reviewed evaluation examples, not automatic training instructions. Test each policy, rule or extraction change against past examples with the appropriate historical policy. Rollback can restore compatible application or model behavior, but it must not silently undo submitted claims, restore revoked access or replace the policy that actually applies to a new expense.
10. A practical production-readiness checklist
Before release, the team should be able to answer each of these questions with evidence:
- Which business task is being improved, and what is the non-AI or simpler baseline?
- Who can access the service, each data source and each tool action?
- How are stale data, deletions and revoked permissions handled?
- Which records are authoritative, why was each storage type chosen, and are schemas, monetary values and state transitions validated?
- Are integration contracts and schema migrations tested, including authorization, idempotency, timeouts and reconciliation after partial failures?
- Which tested versions of the model, prompt, data/index configuration and application form this release?
- Which quality, security and load tests passed—and what are the known limitations?
- What happens when evidence is missing, the model is unavailable or the queue is full?
- Which actions need review, and how are repeated or unauthorized executions prevented?
- What is monitored, what triggers intervention, and who owns the incident response?
- Can a previous approved version be restored without restoring obsolete permissions or unsafe data?
- What is the total cost per useful task, and is it within the agreed operating budget?
My starting point: one expense category, approved sample receipts and policies, one claim-draft schema, deterministic checks, a small evaluation set and a safe review path. Demonstrate the full draft-to-simulated-submission workflow before adding more categories or live integrations. Enterprise readiness is the ability to explain and control each step—not the number of models or boxes in a diagram.